Four frontier models shipped in six weeks. GPT-6 Astra on 3 September. Claude Opus 5.5 on 22 September. Meta’s Muse Wonder on 12 October. Gemini 4 Argon the next day. Each came with a benchmark table and a pricing page.
None of that is how the people using them keep score. They use one word, and it came from the looksmax forums. So we counted it.
The count
We ran X’s post counter on every post from 11 to 18 October (UTC) that pairs mog, mogs, mogged or mogging with a model or lab name: GPT, ChatGPT, Claude, Gemini, OpenAI, Anthropic, Opus, Astra. Retweets excluded. That matched 454 posts. We pulled 435 of them and read each one. 355 really are one AI being ranked against another. The rest were crypto ($MOG), Gemini the star sign, Claude the Fire Emblem character, or people mogging each other with a chatbot tagged in.
| Day (UTC) | Posts matched | Posts that rank AI models |
|---|---|---|
| 12 October | 80 | 69 |
| 13 October | 90 | 73 |
| 14 October | 68 | 57 |
| 15 October | 69 | 45 |
| 16 October | 47 | 36 |
| 17 October | 59 | 47 |
That’s 36 to 73 a day, every day, with a peak on the two days Meta and Google launched. It isn’t a trend. It has simply become the default verb for this model beat that one.
Who mogs whom
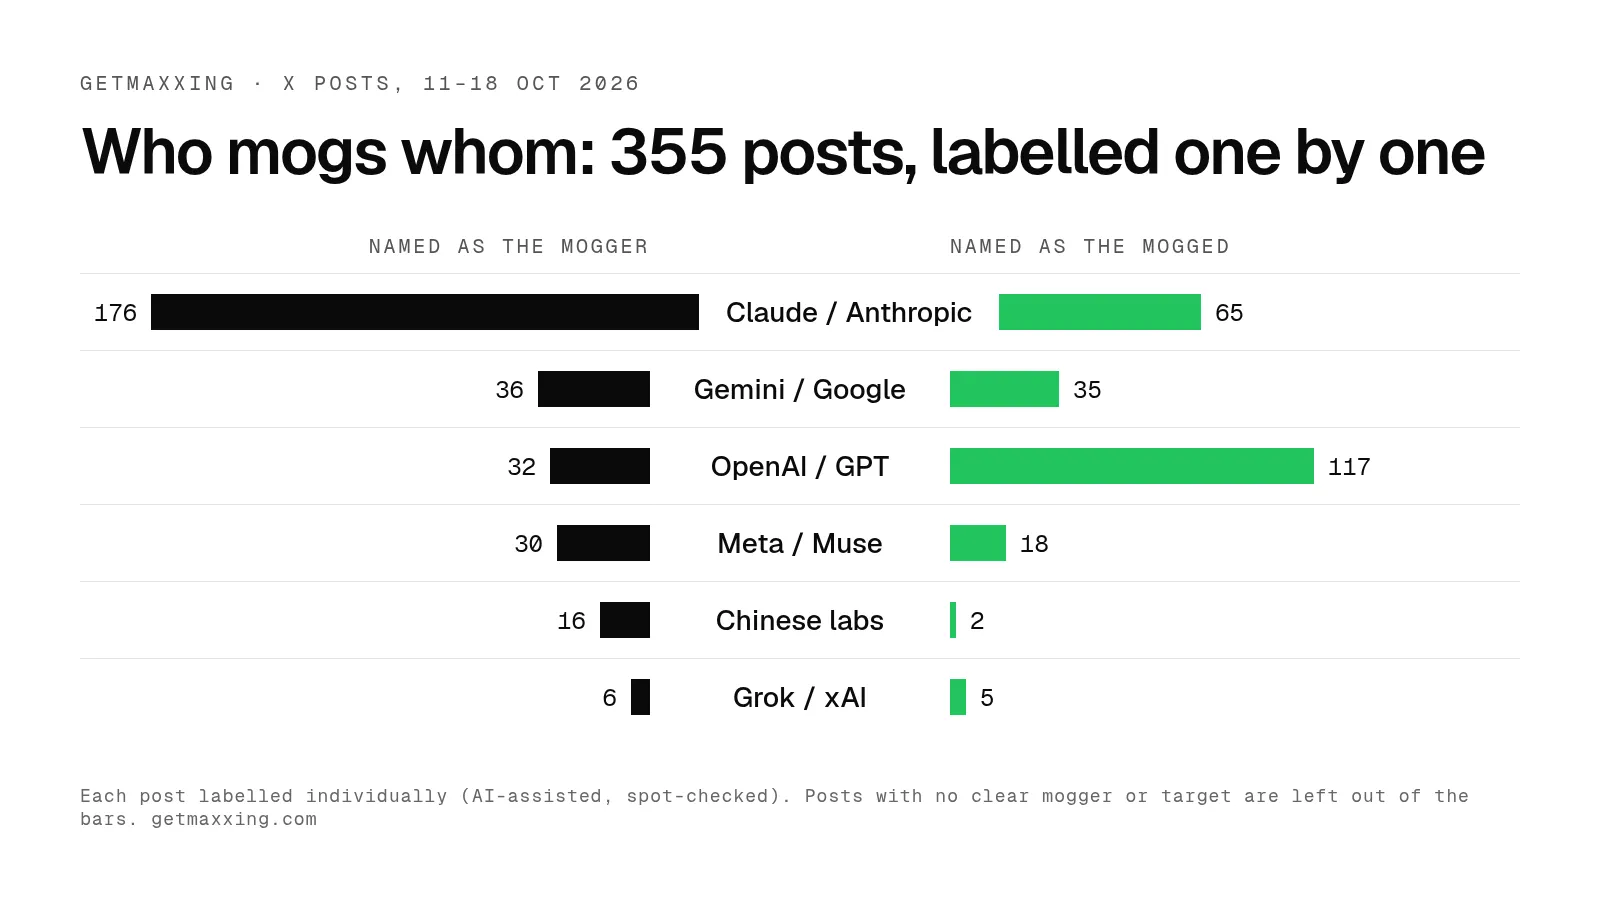
Of the 304 posts that name a winner, 176 (58%) name Claude. Of the 248 that name a loser, 117 (47%) name OpenAI. Where both sides are named, Claude mogs OpenAI 75 times. OpenAI mogs Claude 17 times. That’s 4.4 to 1.
| Lab | Named as mogger | Named as mogged |
|---|---|---|
| Claude / Anthropic | 176 | 65 |
| Gemini / Google | 36 | 35 |
| OpenAI / GPT | 32 | 117 |
| Meta / Muse | 30 | 18 |
| Chinese labs (DeepSeek and others) | 16 | 2 |
| Grok / xAI | 6 | 5 |
The most-viewed post in our set wasn’t about Claude at all. On launch day, Meta got its turn.
how is OPENAI getting mogged by fucking META?
— maria (@maria_rcks) October 12, 2026
Meta appears in 33 posts on 12 October and one on 17 October. Beff Jezos (310K followers) said Wonder “definitely mogged Astra in my hardcore physics testing”, and Alexandr Wang, who runs Meta’s AI lab, posted the quote himself that evening. Google shipped Argon the next day, and by Wednesday the posts had Argon mogging Wonder.
The week’s biggest receipts
| Post | Claim | Views | Likes |
|---|---|---|---|
| @maria_rcks | OpenAI mogged by Meta | 269.6K | 769 |
| @vib3coded | Opus 5.5 mogged Astra, Fable and Sonnet (jelly test) | 142.9K | 1,142 |
| @0x0SojalSec | Opus 5.5 mogged Gemini 4 Argon | 64.3K | 321 |
| @beffjezos | Muse Wonder mogged Astra (physics) | 43.5K | 441 |
| @SahilPanhotra | DeepSeek V4.1 Flash mogging Opus 5.5 | 36.6K | 984 |
The tests are as far from a benchmark as possible: a jelly slice that has to wobble right, an Eiffel Tower, a physics toy. The accounts aren’t looksmaxxers either. Saurabh Kumar (21.4K followers) wrote two careful sentences about long-horizon tasks, then closed on “Opus mogs OAI so hard.” A Spanish-language account with 30.2K followers wrote its whole comparison in Spanish and ended on one English word: “Mogged.”
The budget mog, checked
GEMINI 4 ARGON JUST MOGGED OPUS 5.5’S BUDGET💀 Same task: build the Eiffel Tower. Opus 5.5 → $33.45 Gemini 4 Argon → $0.23 that’s a 145× price gap.
— noclipepe (@noclipepe) October 17, 2026
That’s one person’s test, and we haven’t reproduced it. The price list we can check, using benchr’s recorded API rates per million input / output tokens:
| Model | Input | Output |
|---|---|---|
| GPT-6 Astra | $10 | $50 |
| Claude Opus 5.5 | $4 | $20 |
| Muse Wonder | $4 | $20 |
| Gemini 4 Argon (introductory) | $2 | $10 |
| Gemini 4 Argon (from 1 December) | $4 | $20 |
| DeepSeek V4.1 Flash | $0.30 | $1.20 |
On list price, Argon is 2× cheaper than Opus, not 145×. If the Eiffel Tower bill is real, the other ~72× comes from how many tokens each model chose to burn on the same job. That’s a more interesting finding than the post makes it sound, and the 2× disappears on 1 December, when Argon moves to Opus’s price. The “5× less” in @0x0SojalSec’s post doesn’t match the list either.
Why this word
It fits suspiciously well. Mogging was always about a side-by-side: two faces, one frame, let the gap speak. That’s exactly what model comparisons are now: same prompt, two outputs, screenshot, verdict. The forums built a vocabulary for ranking things in pairs, and the industry that ranks things in pairs all day picked it up.
There’s also the tokenmaxxing irony. The crowd that spent a year optimising prompts and token budgets now scores itself with a word for whose jaw is wider.
How we counted
- Window: 11 October 12:03 to 18 October 12:03 UTC, through X’s recent-search counter and search API. Retweets excluded. Daily rows are full UTC days.
- Grok left out of the search: “mog” plus “Grok” mostly returns people tagging @grok into arguments, so Grok only counts when a post found by the other terms names it. Its numbers are a floor.
- Labelling: each of the 435 posts was labelled individually (AI-assisted, then spot-checked by us) as relevant or not, with a mogger and a mogged where the post names them. “Mogs everything” counts as a mogger with no target. Where a post names several losers, only the first counts.
- Limits: X search doesn’t return every post, so 19 matched posts never came back. Search samples X, not the internet. A post is one person’s opinion: this measures who people say mogs, not who wins. View counts were captured on 18 October.
Last week, a stan account told a Felix fan that a man could never mog a woman, and 95,000 people agreed. This week Claude mogs OpenAI 75 to 17, Meta mogged for exactly one day, and somebody is already testing whether the next one mogs Astra.
The benchmark has a new unit. It’s the mog.


